Why teams outgrow DeepEval alone
DeepEval gets you started. Enterprise gets you standardized.
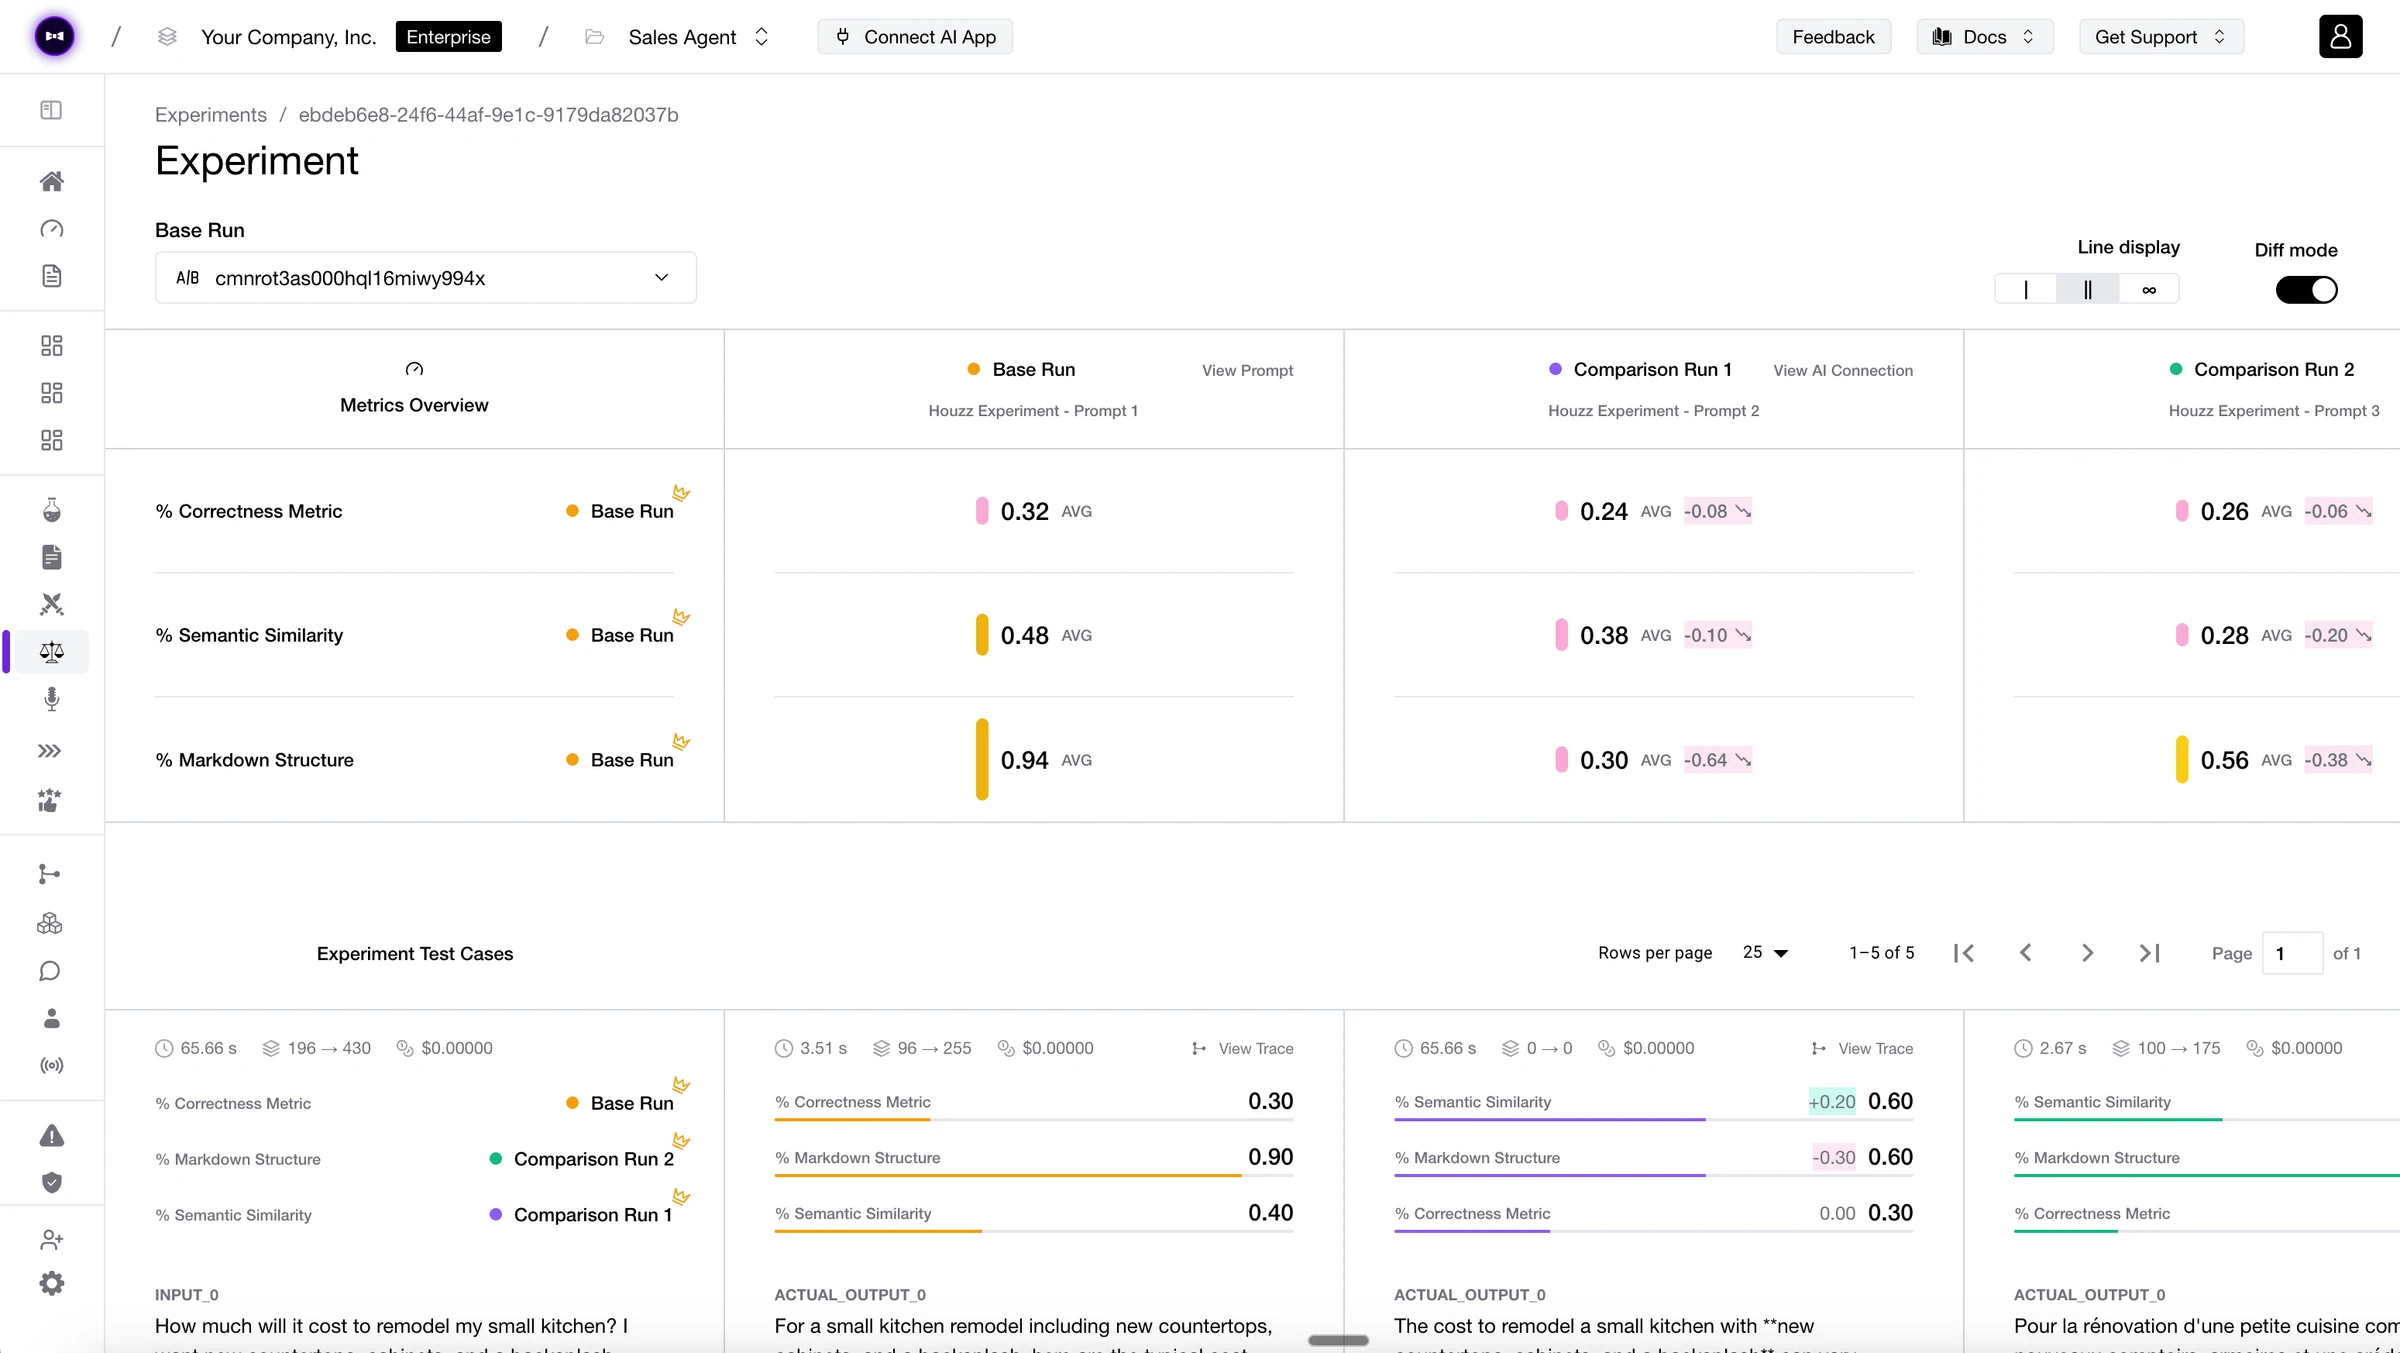
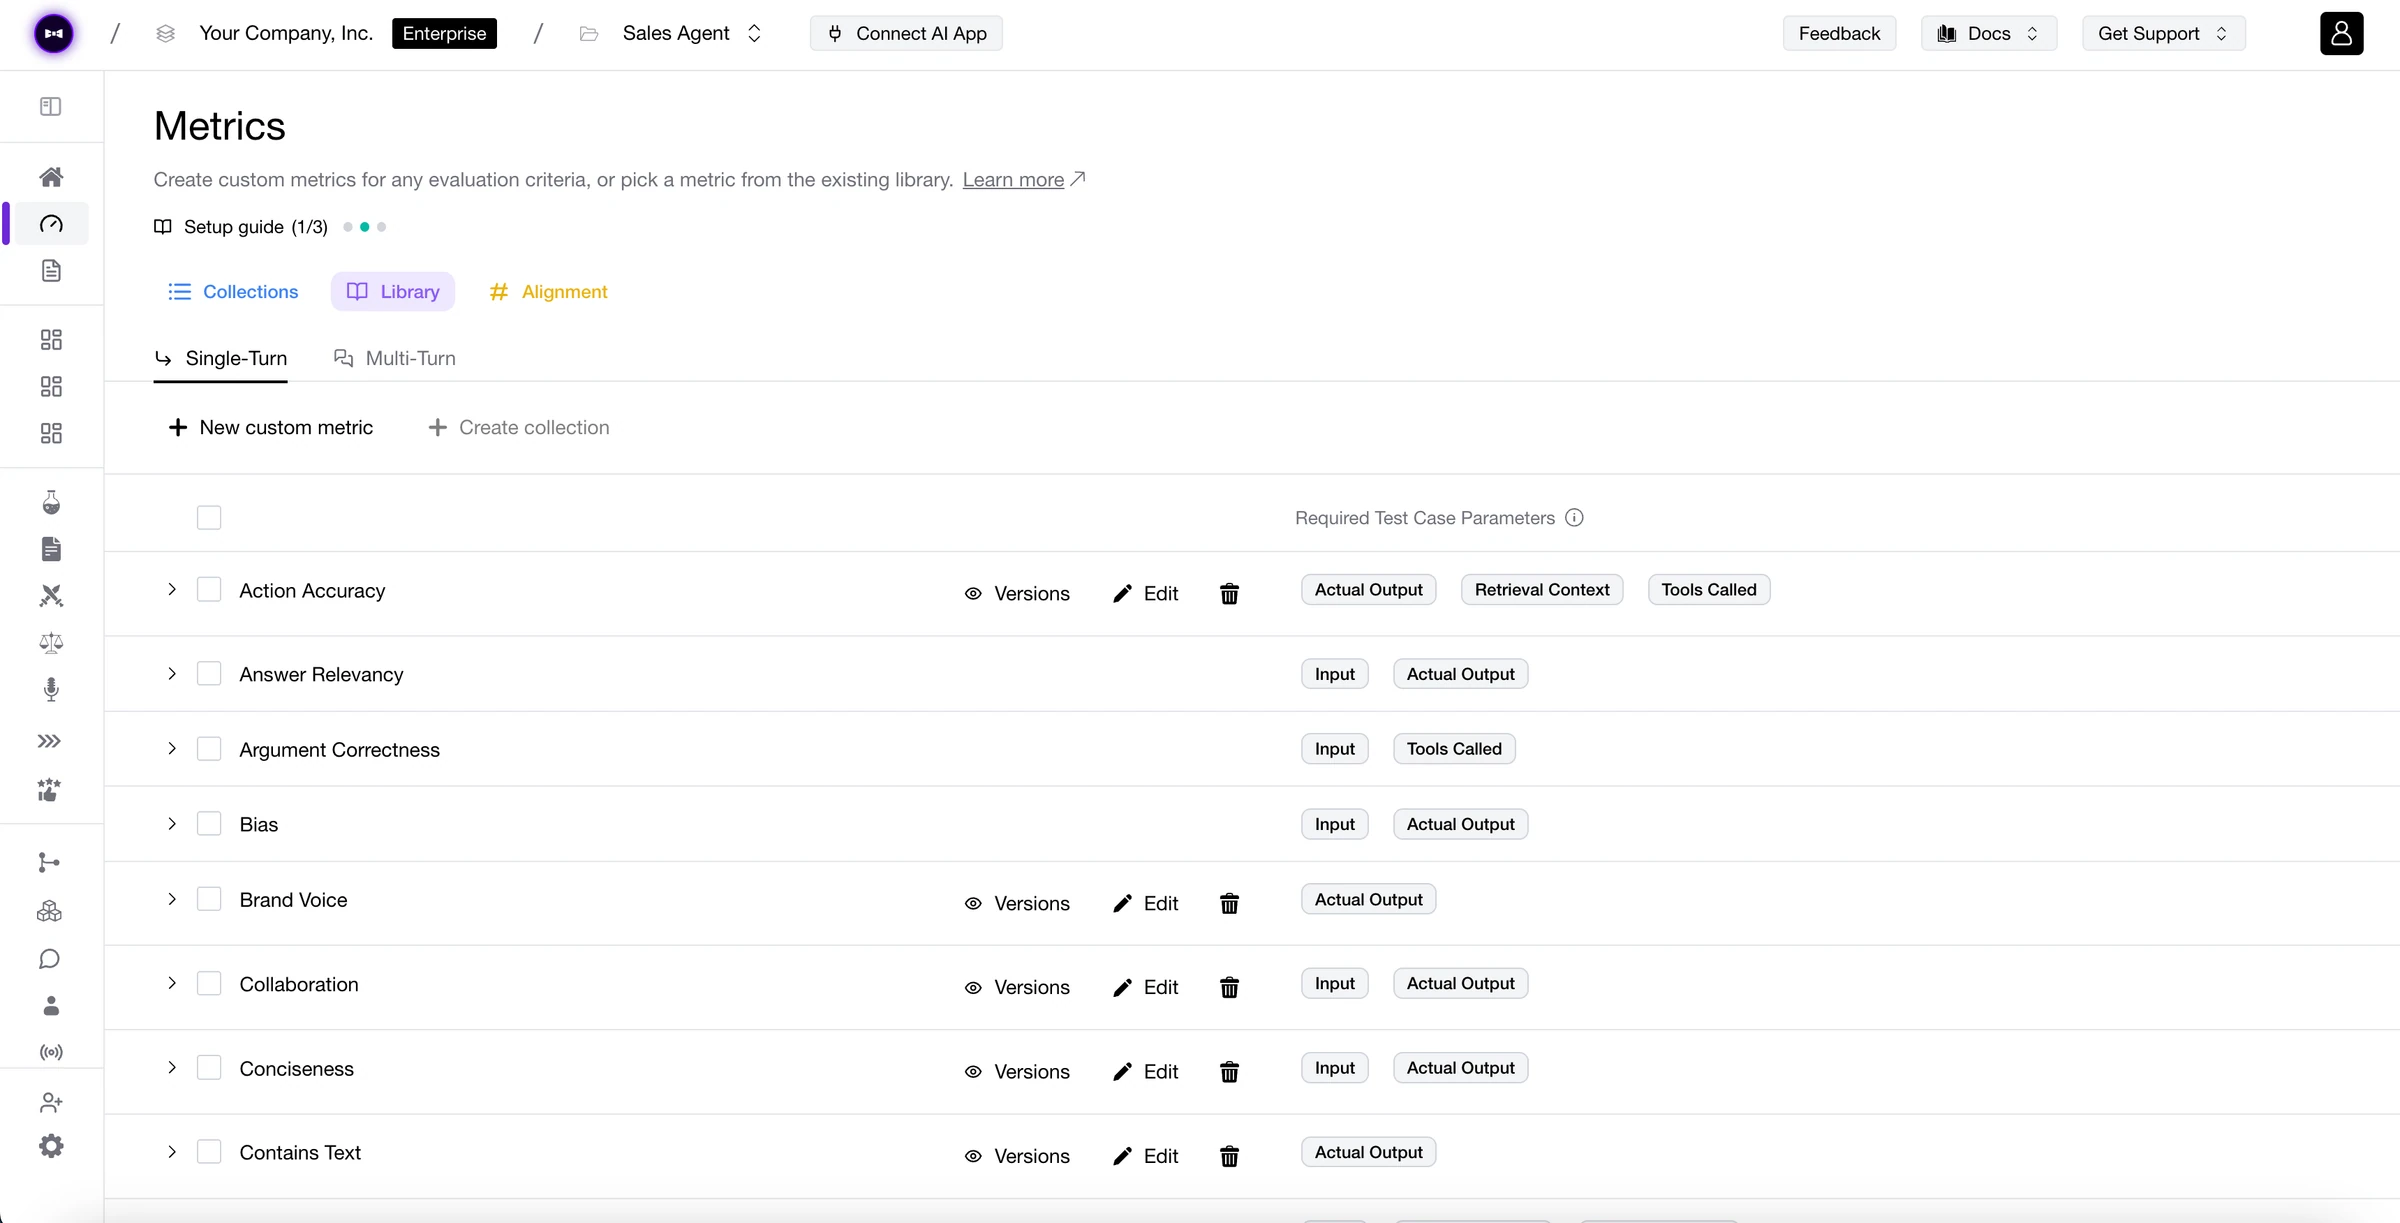
For enterprise teams, Confident AI is one system for AI quality: evaluation, monitoring, annotation, red teaming and governance, with one standard every team ships against. DeepEval evaluates your app in development. Confident AI enforces the standard once it's live, running evals on every production trace and turning the failing ones into your next eval.
For product and QA teams
Everyone works from the same failing traces.
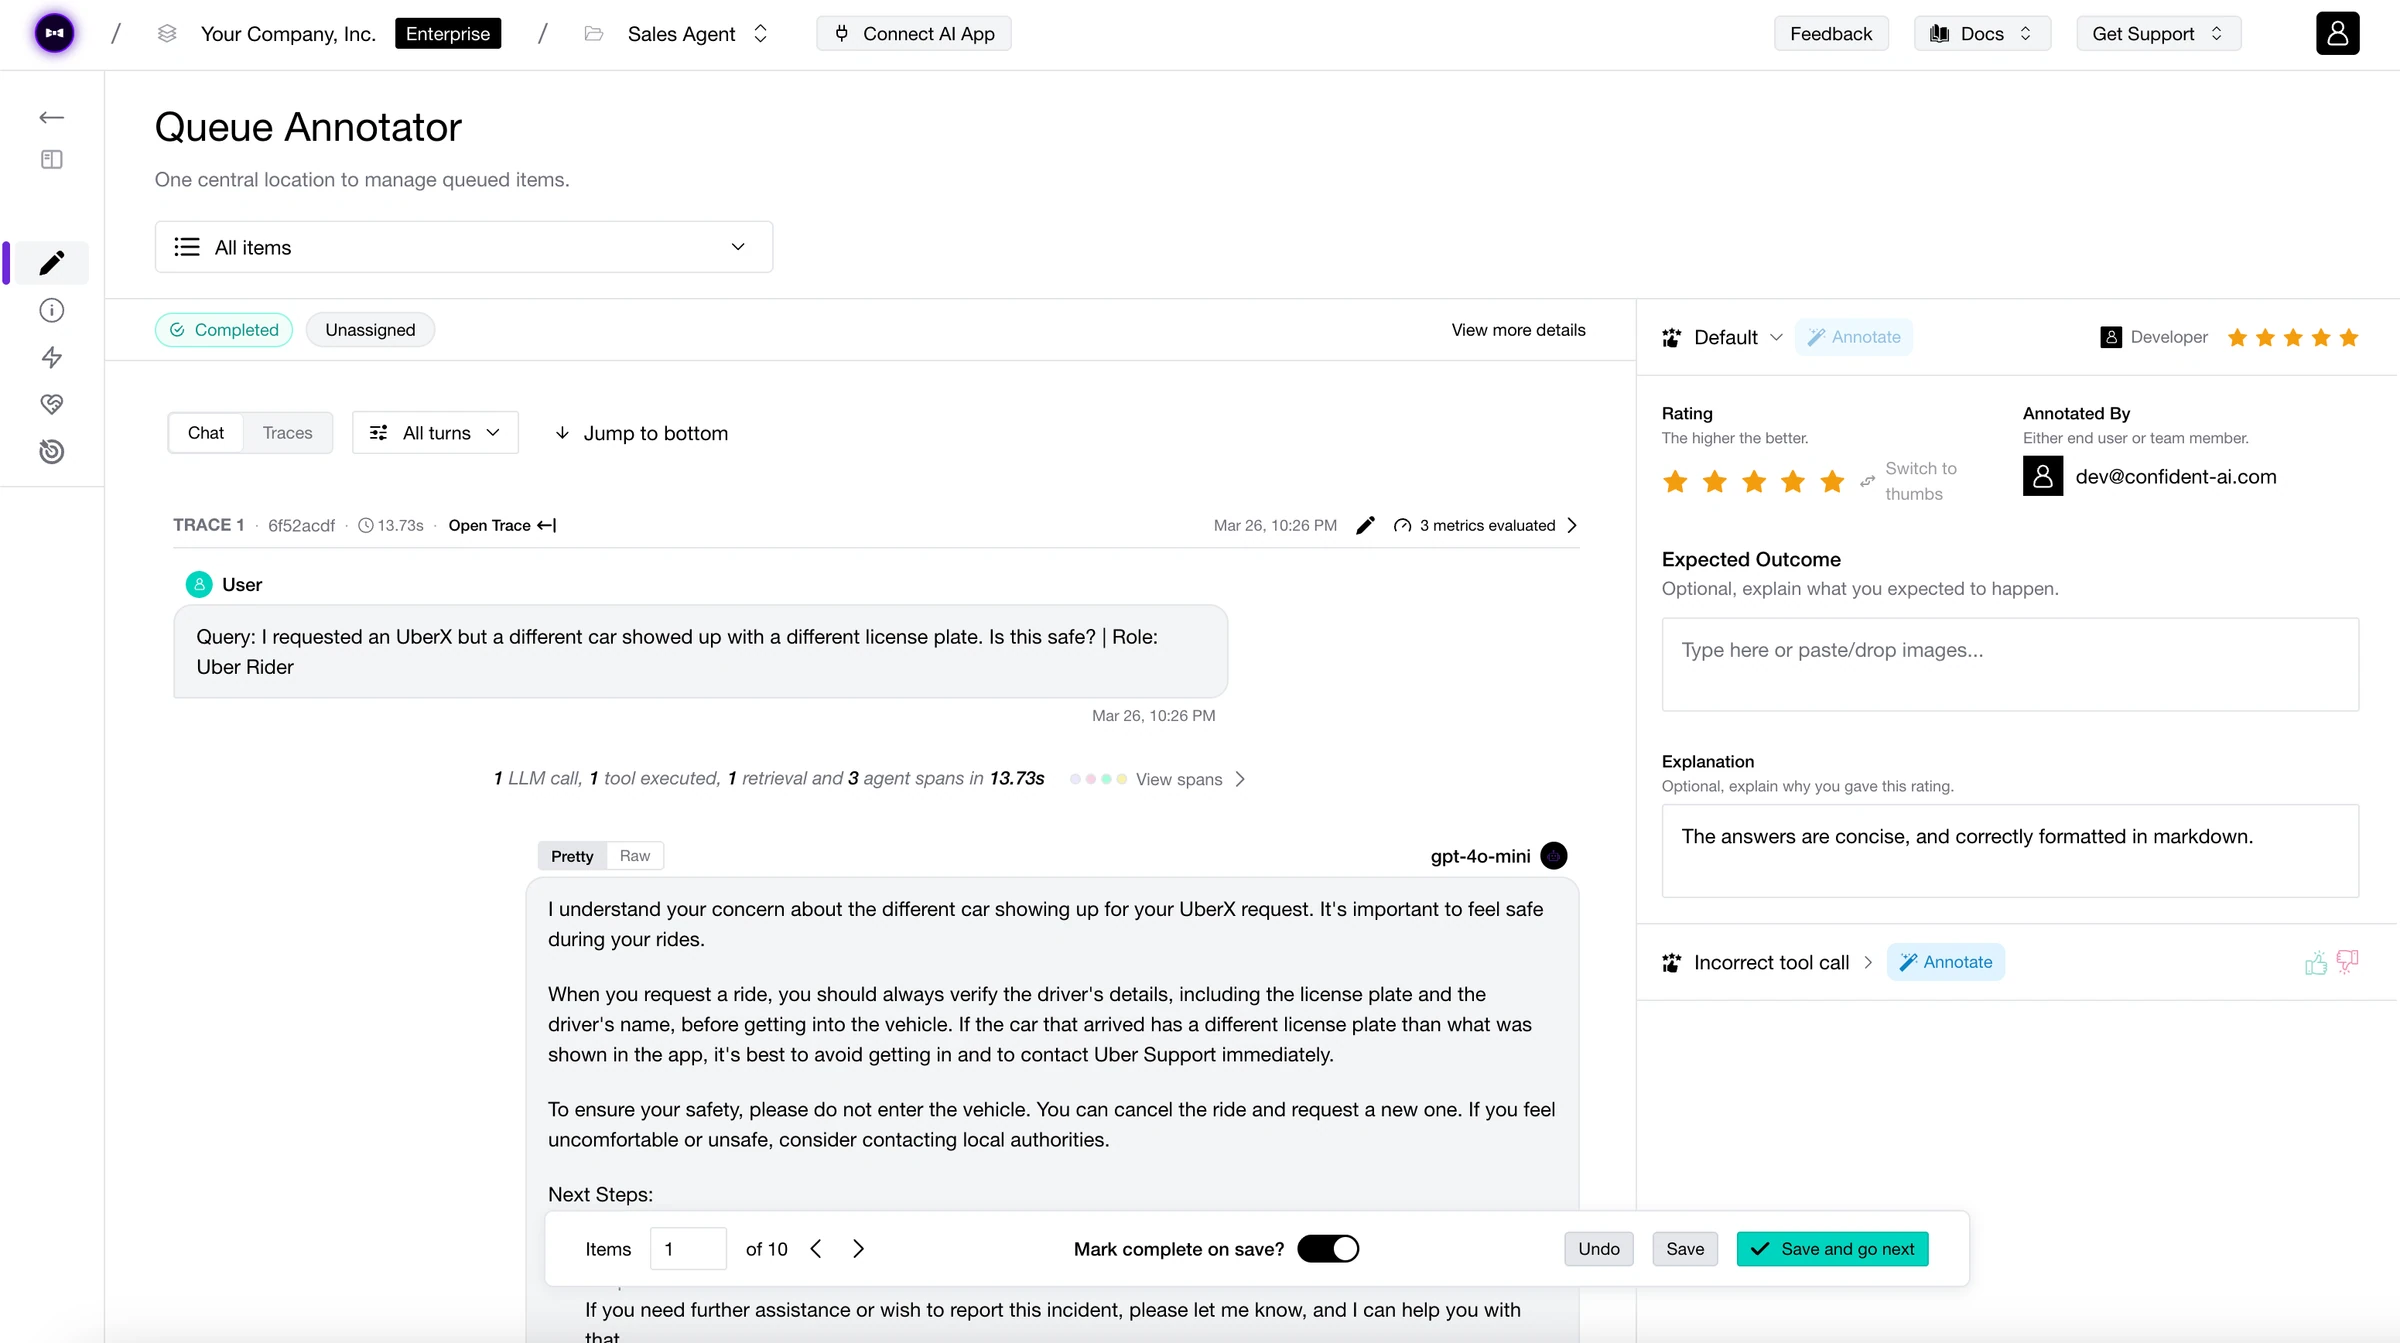
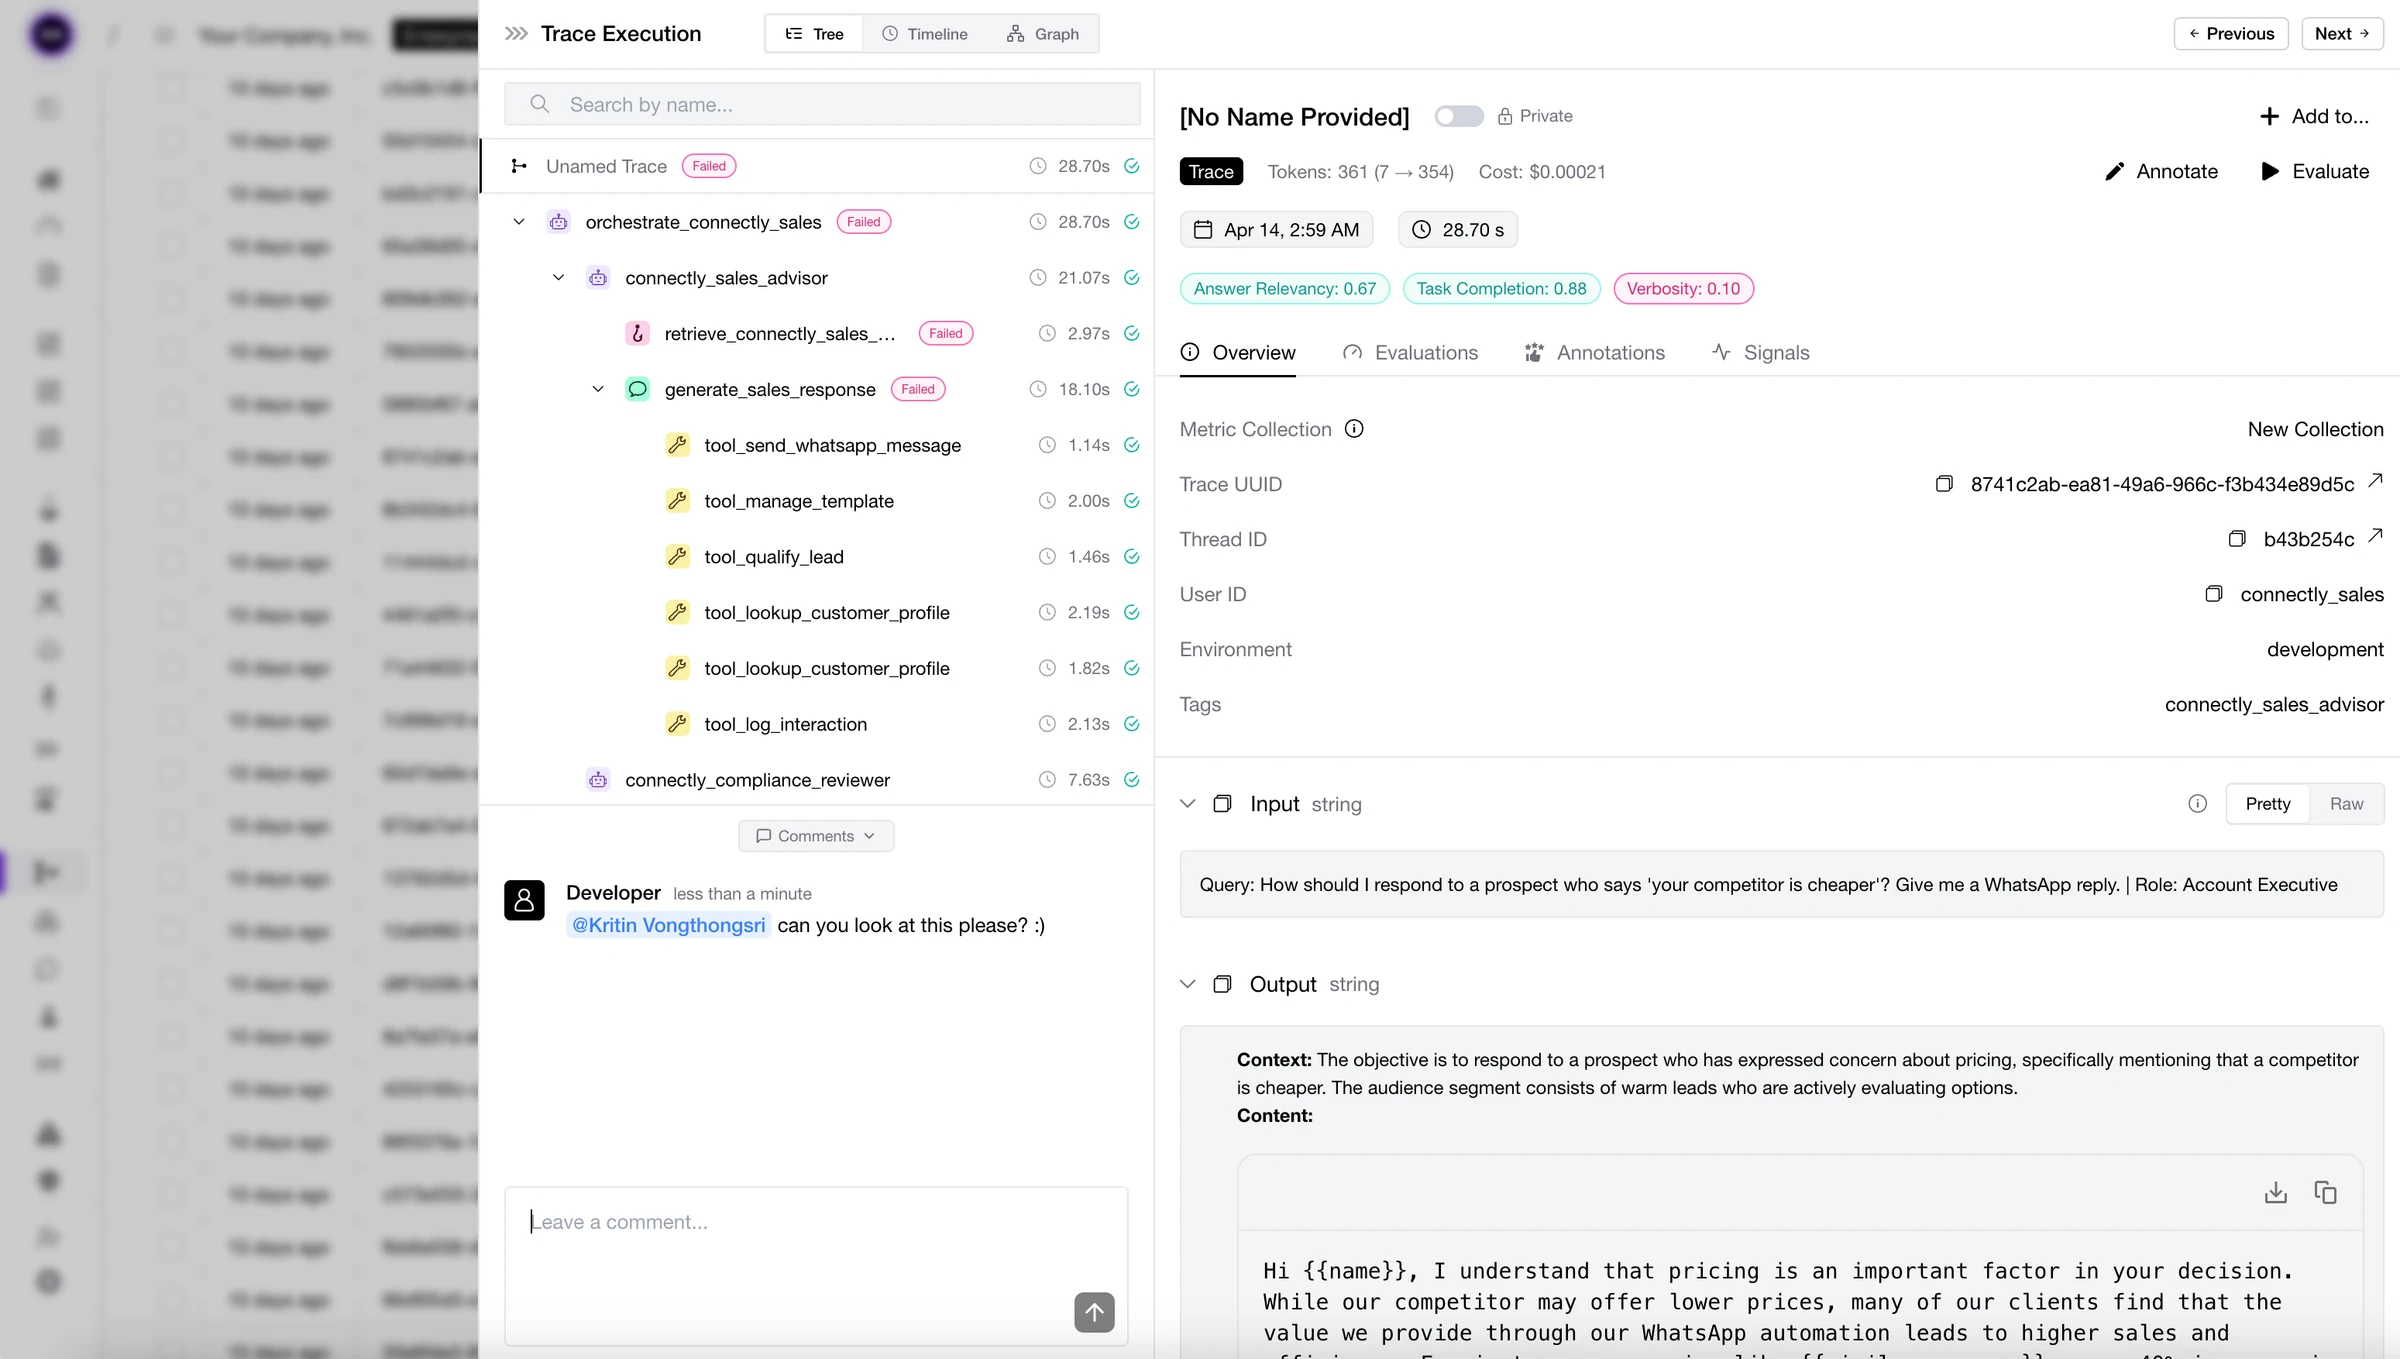
Engineers, QA, domain experts and PMs work from the same traces, annotations and datasets, so PMs stay in the loop on what's failing and why. Nobody files a ticket to engineering to find out which traces broke.
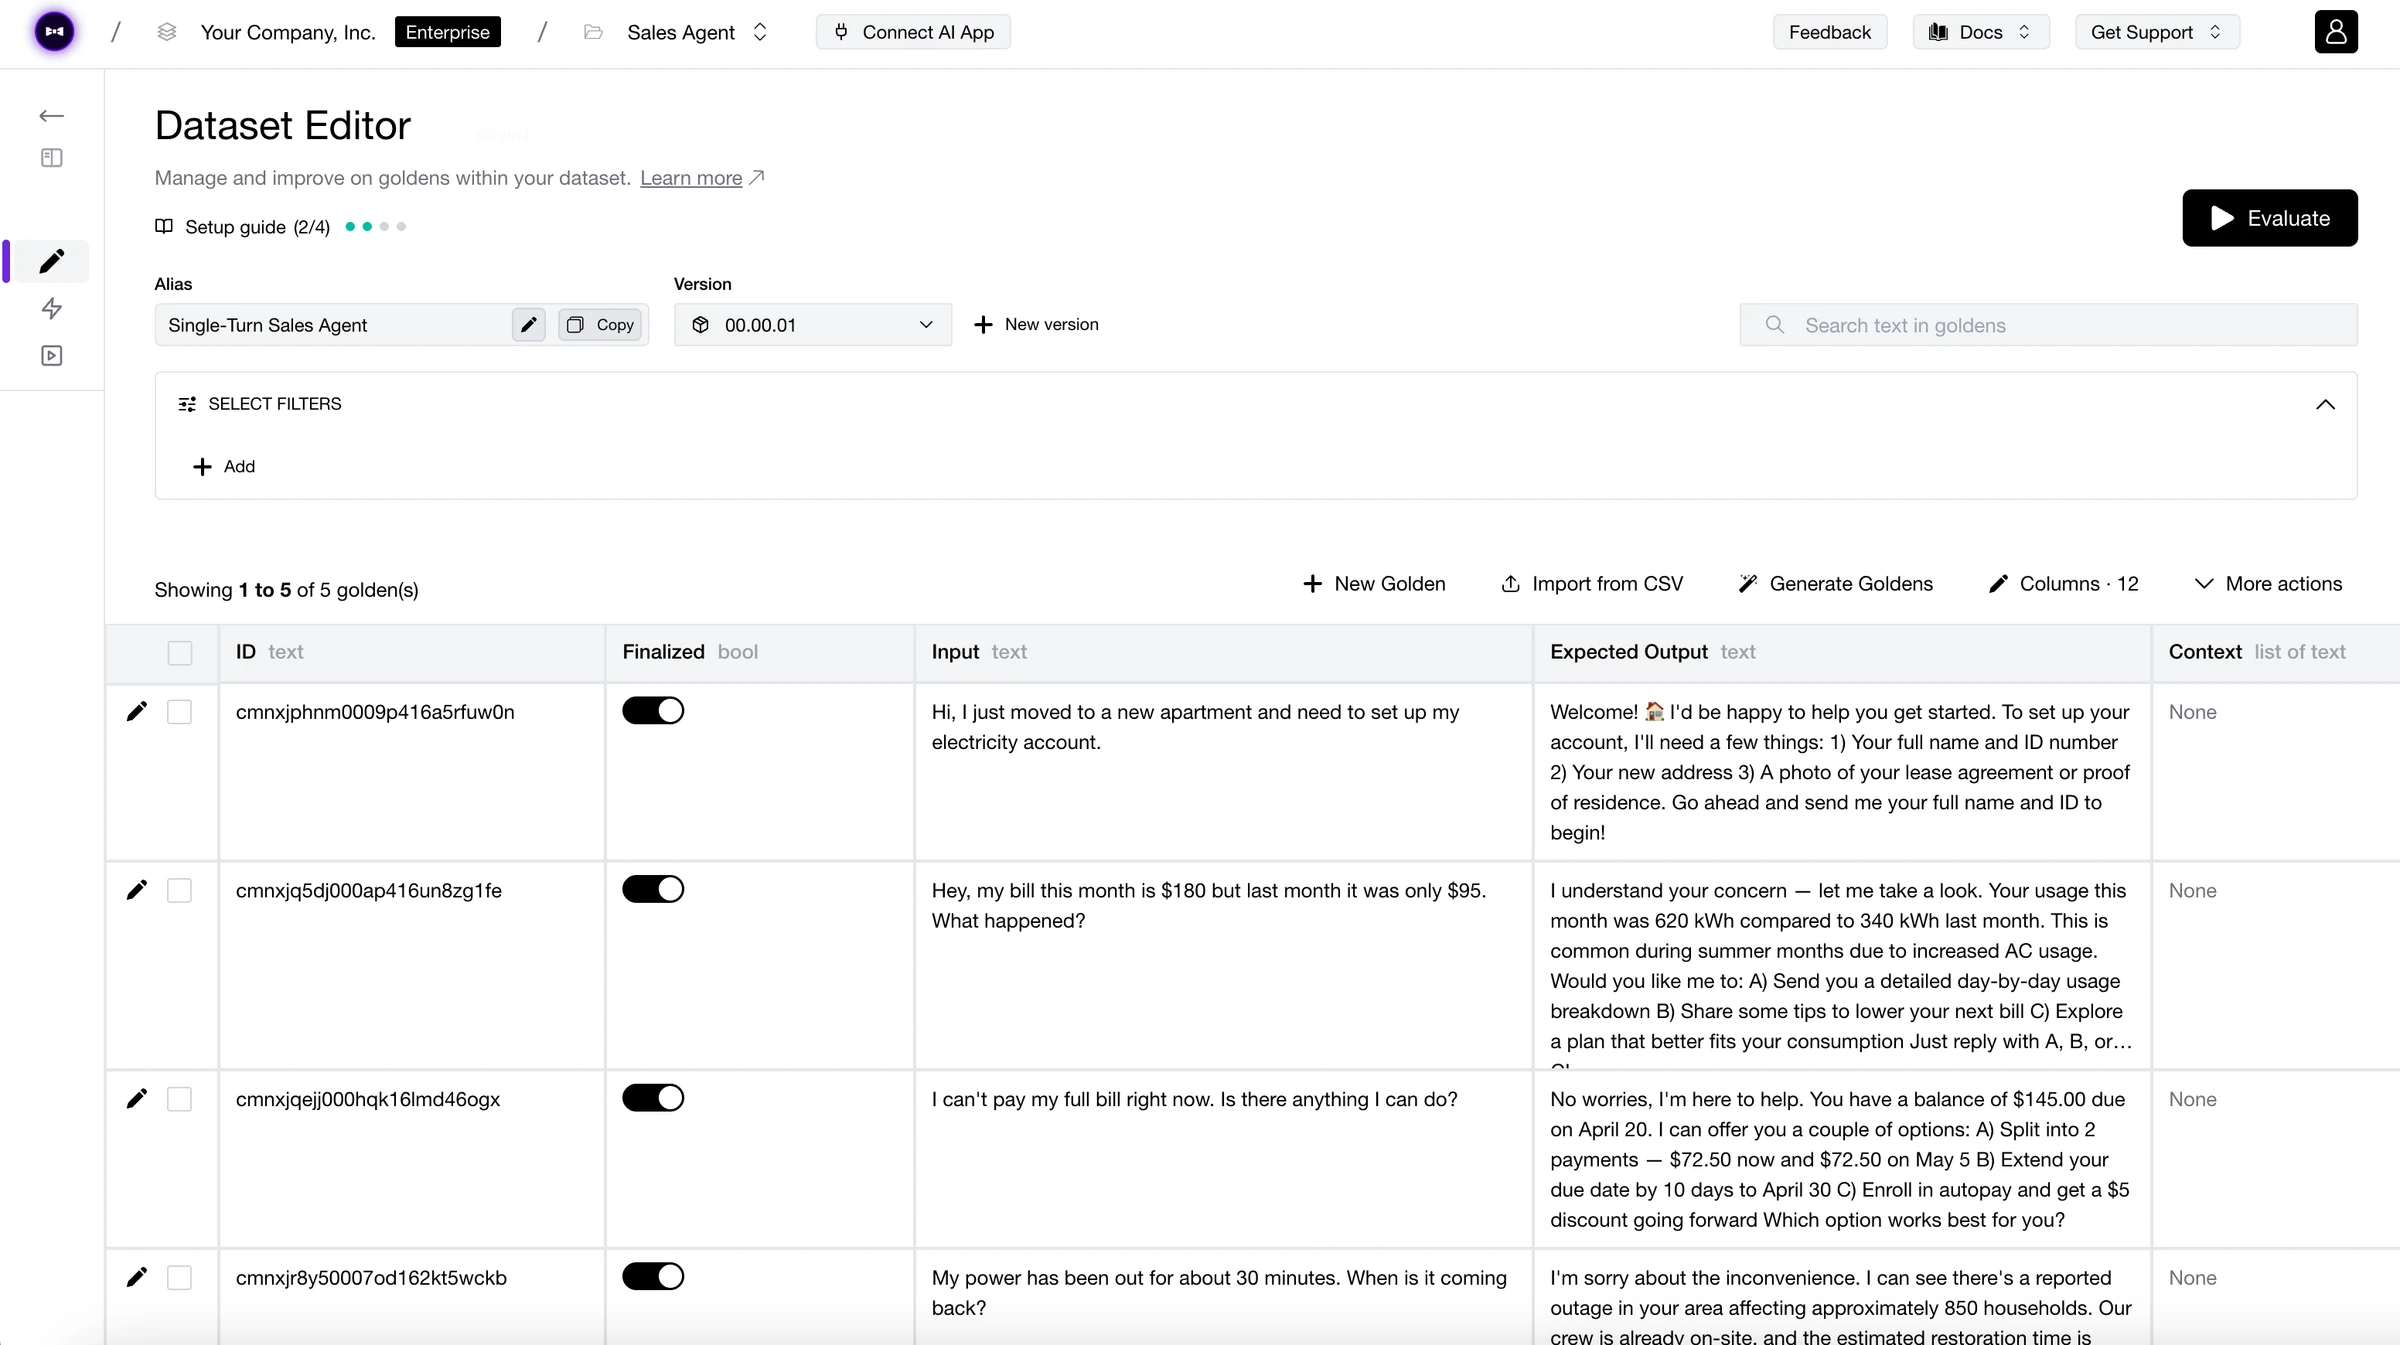
- Failing traces routed to the right annotators, who turn them into goldens.
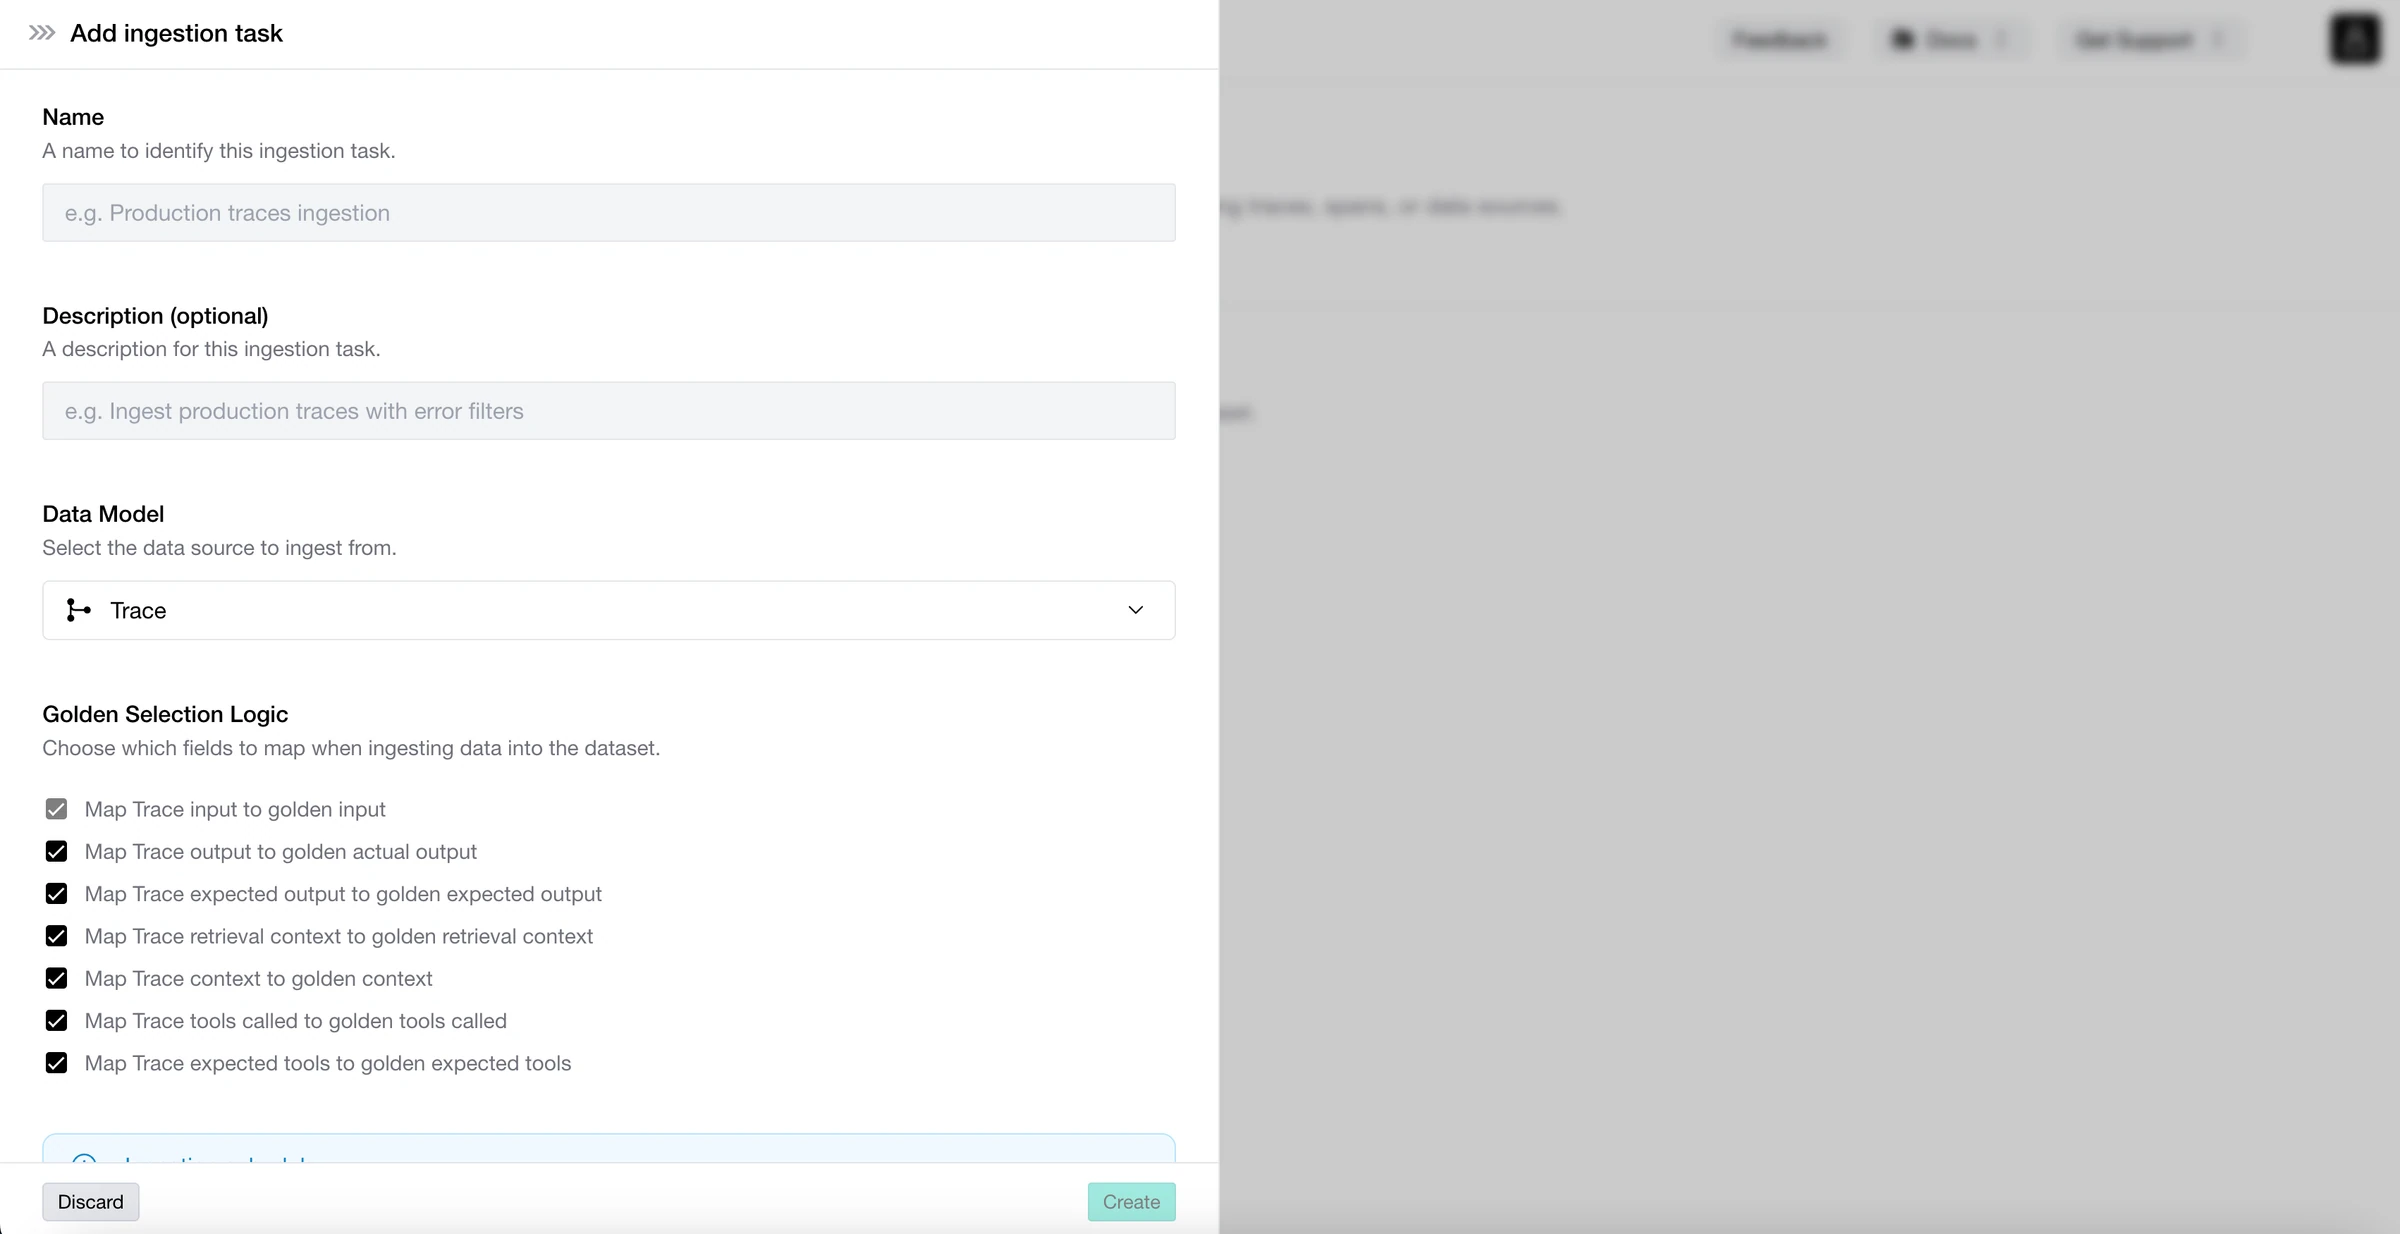
- Datasets built from failing production traces, ready for the next eval.
- Connects to your AI app over HTTP, so non-technical team members can contribute without touching code.
For engineering teams
Failing production traces become your next eval.
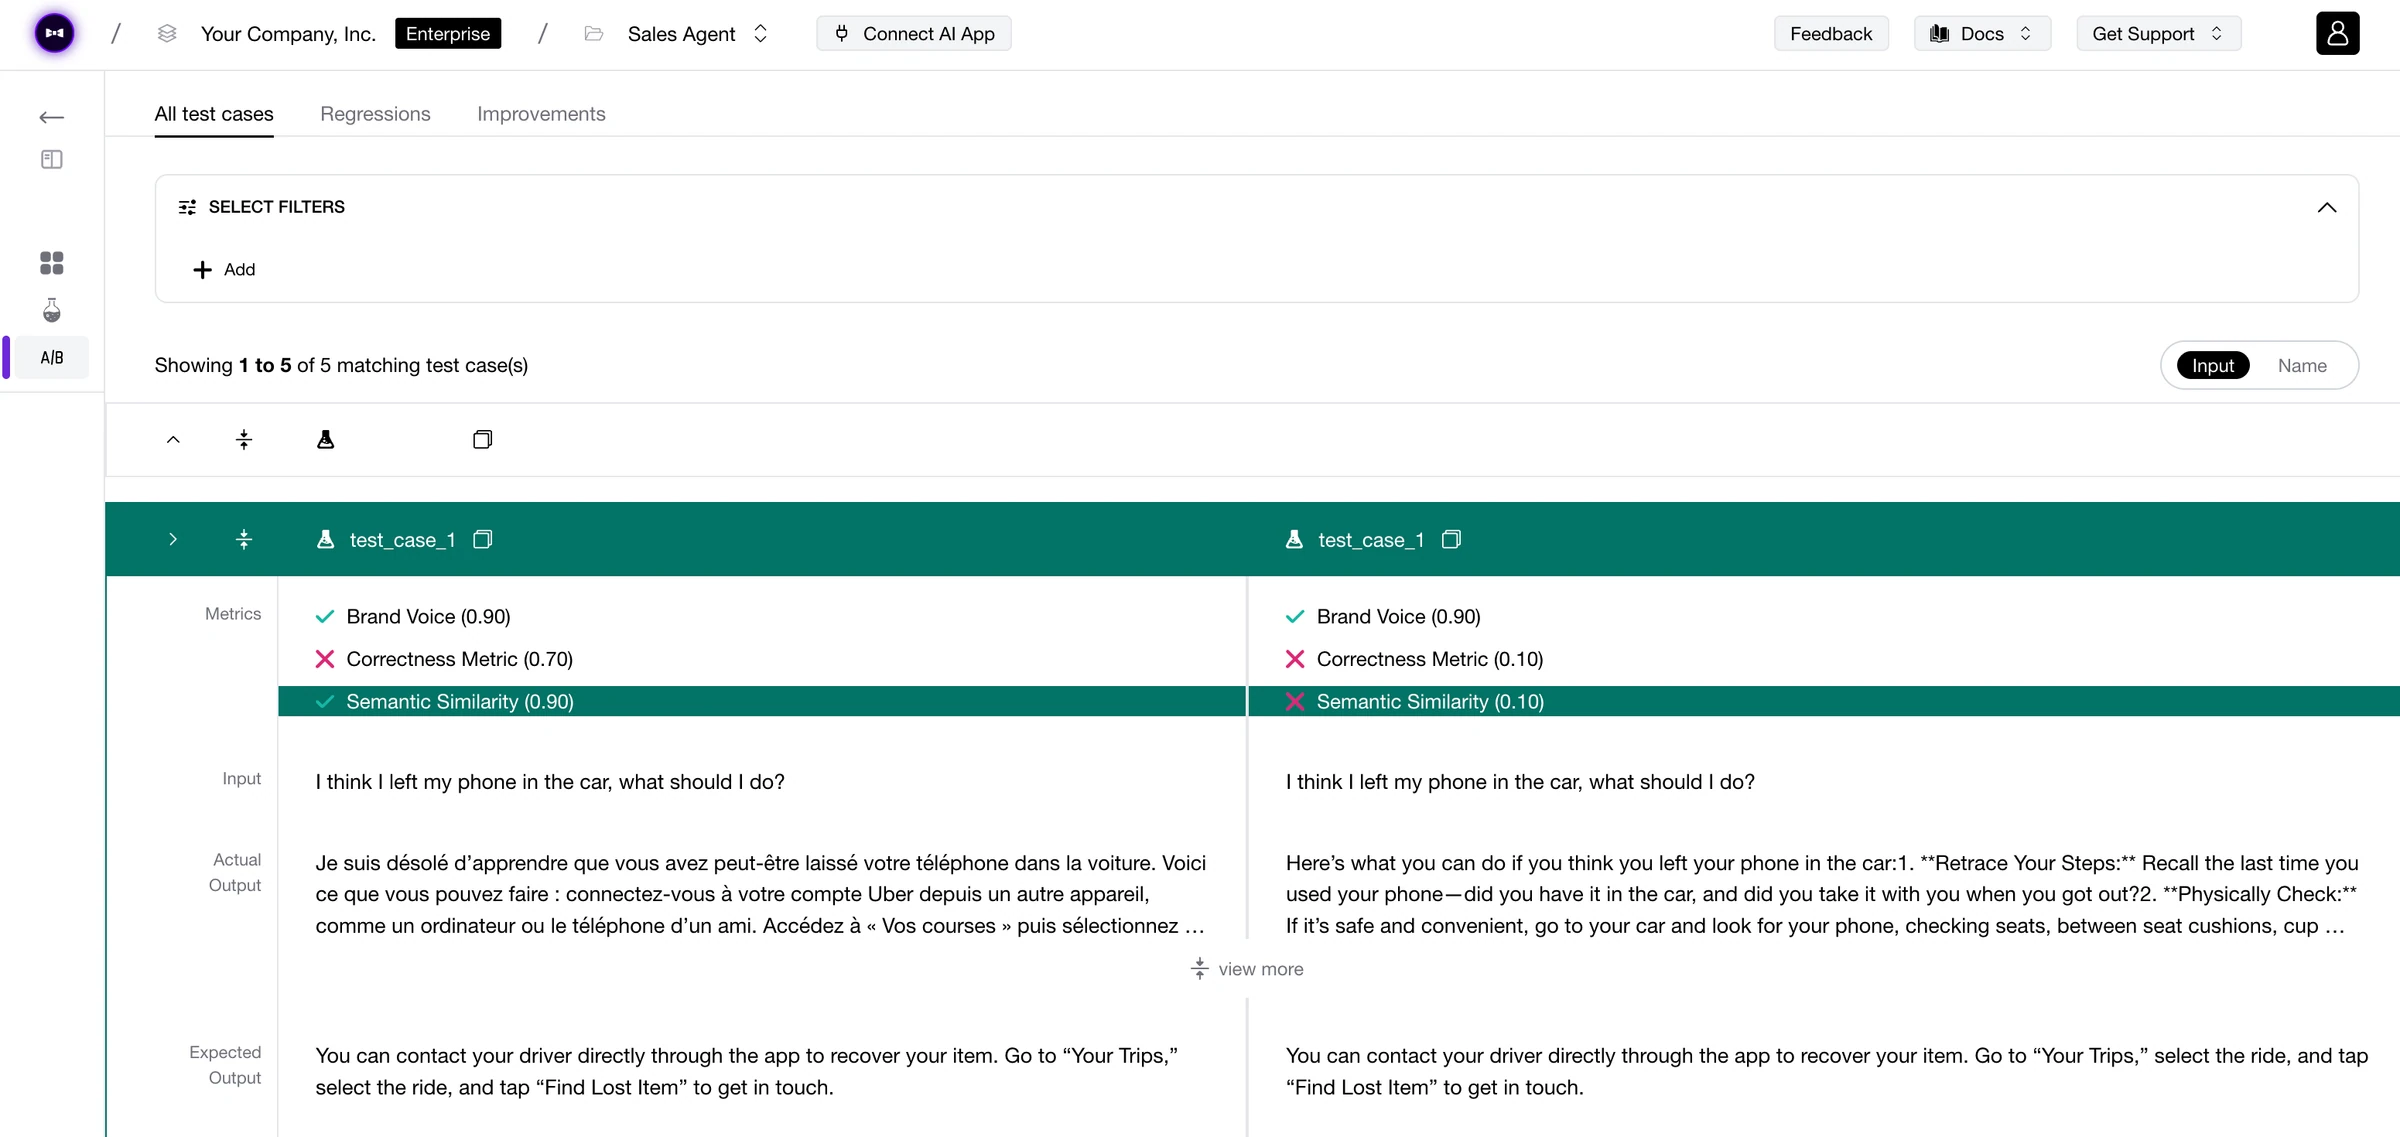
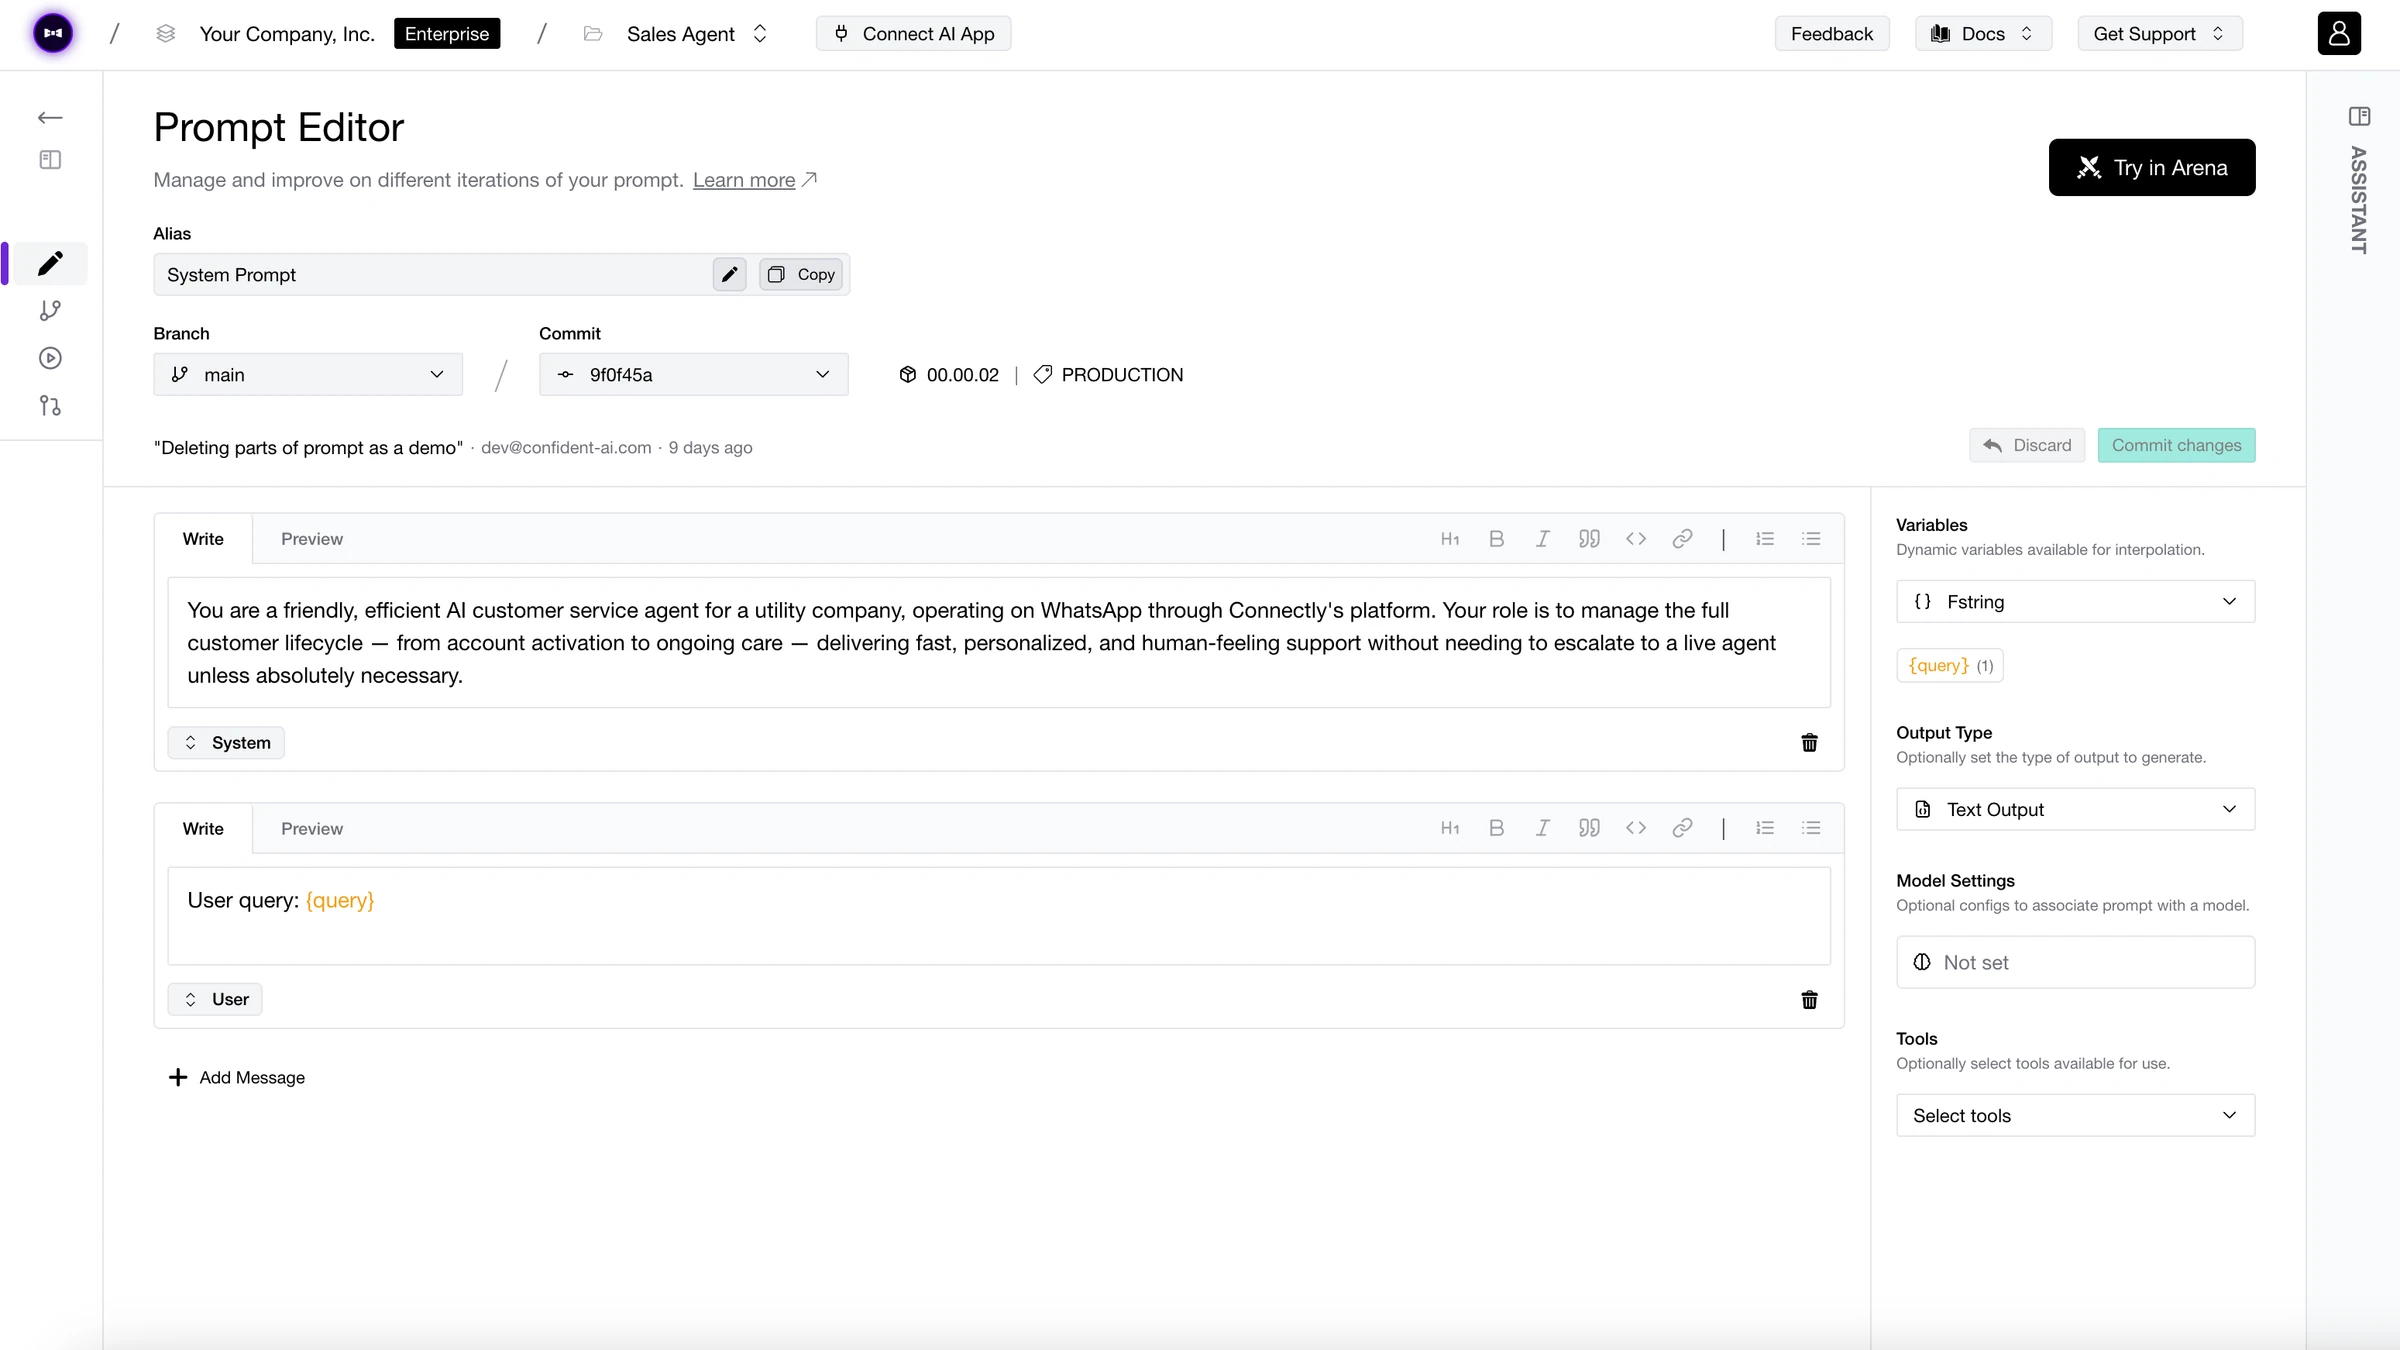
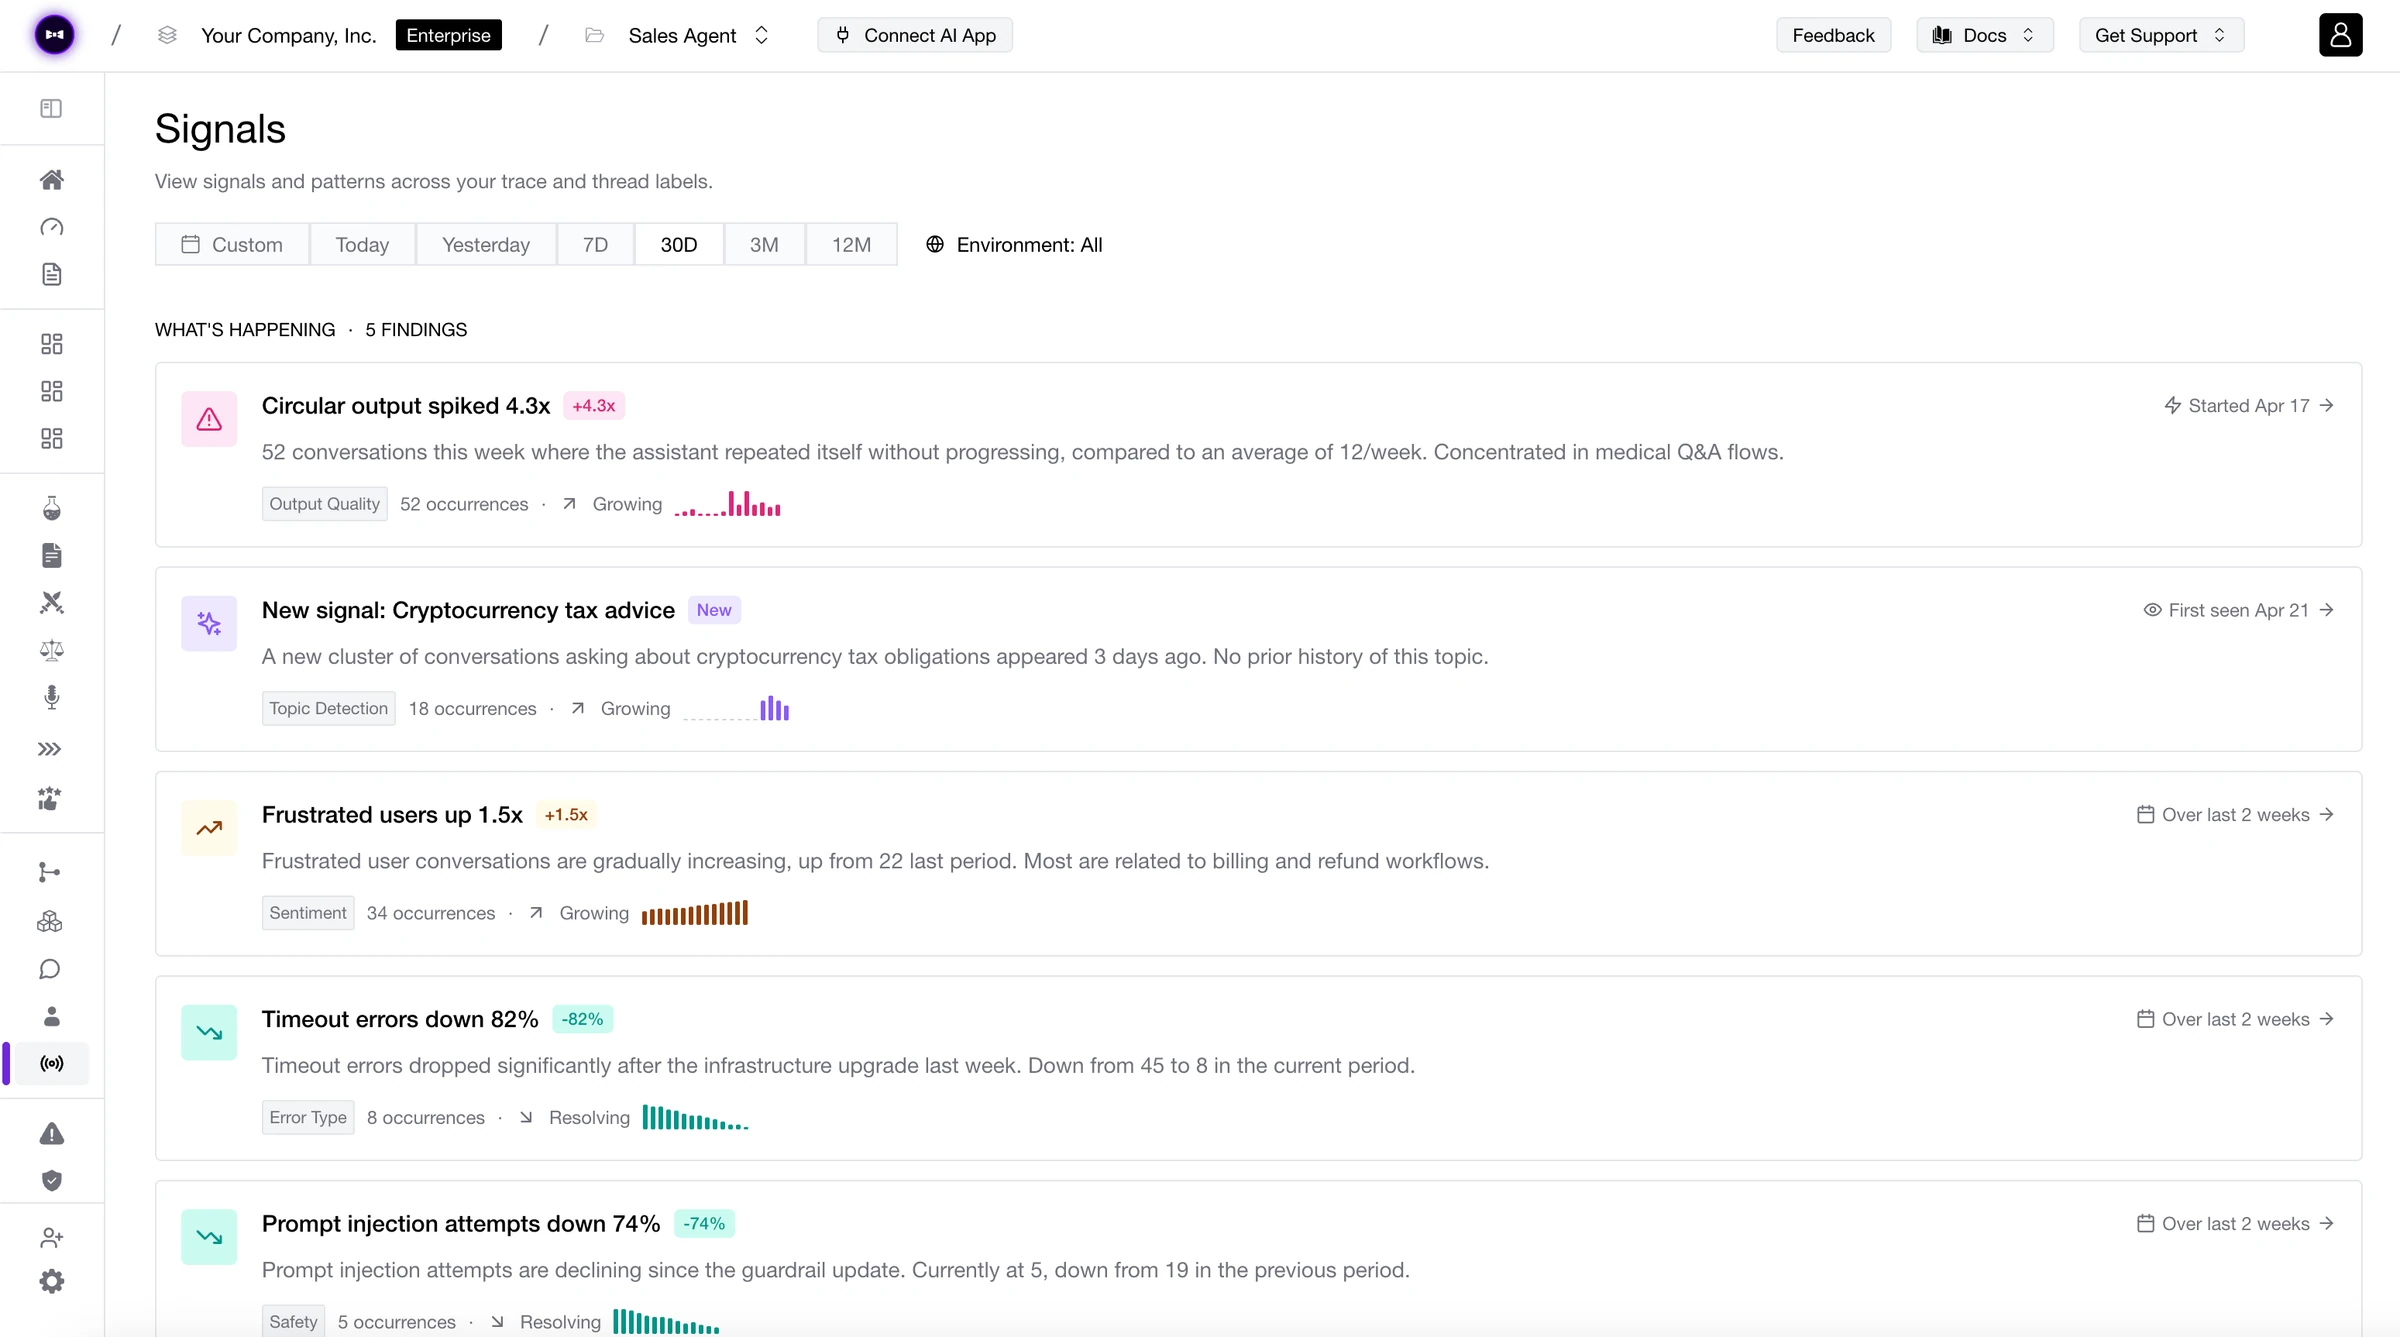
Instrument once with OpenTelemetry or a framework integration (LangChain, LangGraph, CrewAI, OpenAI Agents, Pydantic AI, or your own stack). Confident AI surfaces failing production traces before anyone has written an eval for them, clusters them into failure modes, and turns them into goldens for your next eval. Detect the failure, build the eval, then run it on every trace from then on.
- Failure modes shown alongside user sentiment and behavior across traces.
- Failing traces turned into datasets for the next eval.
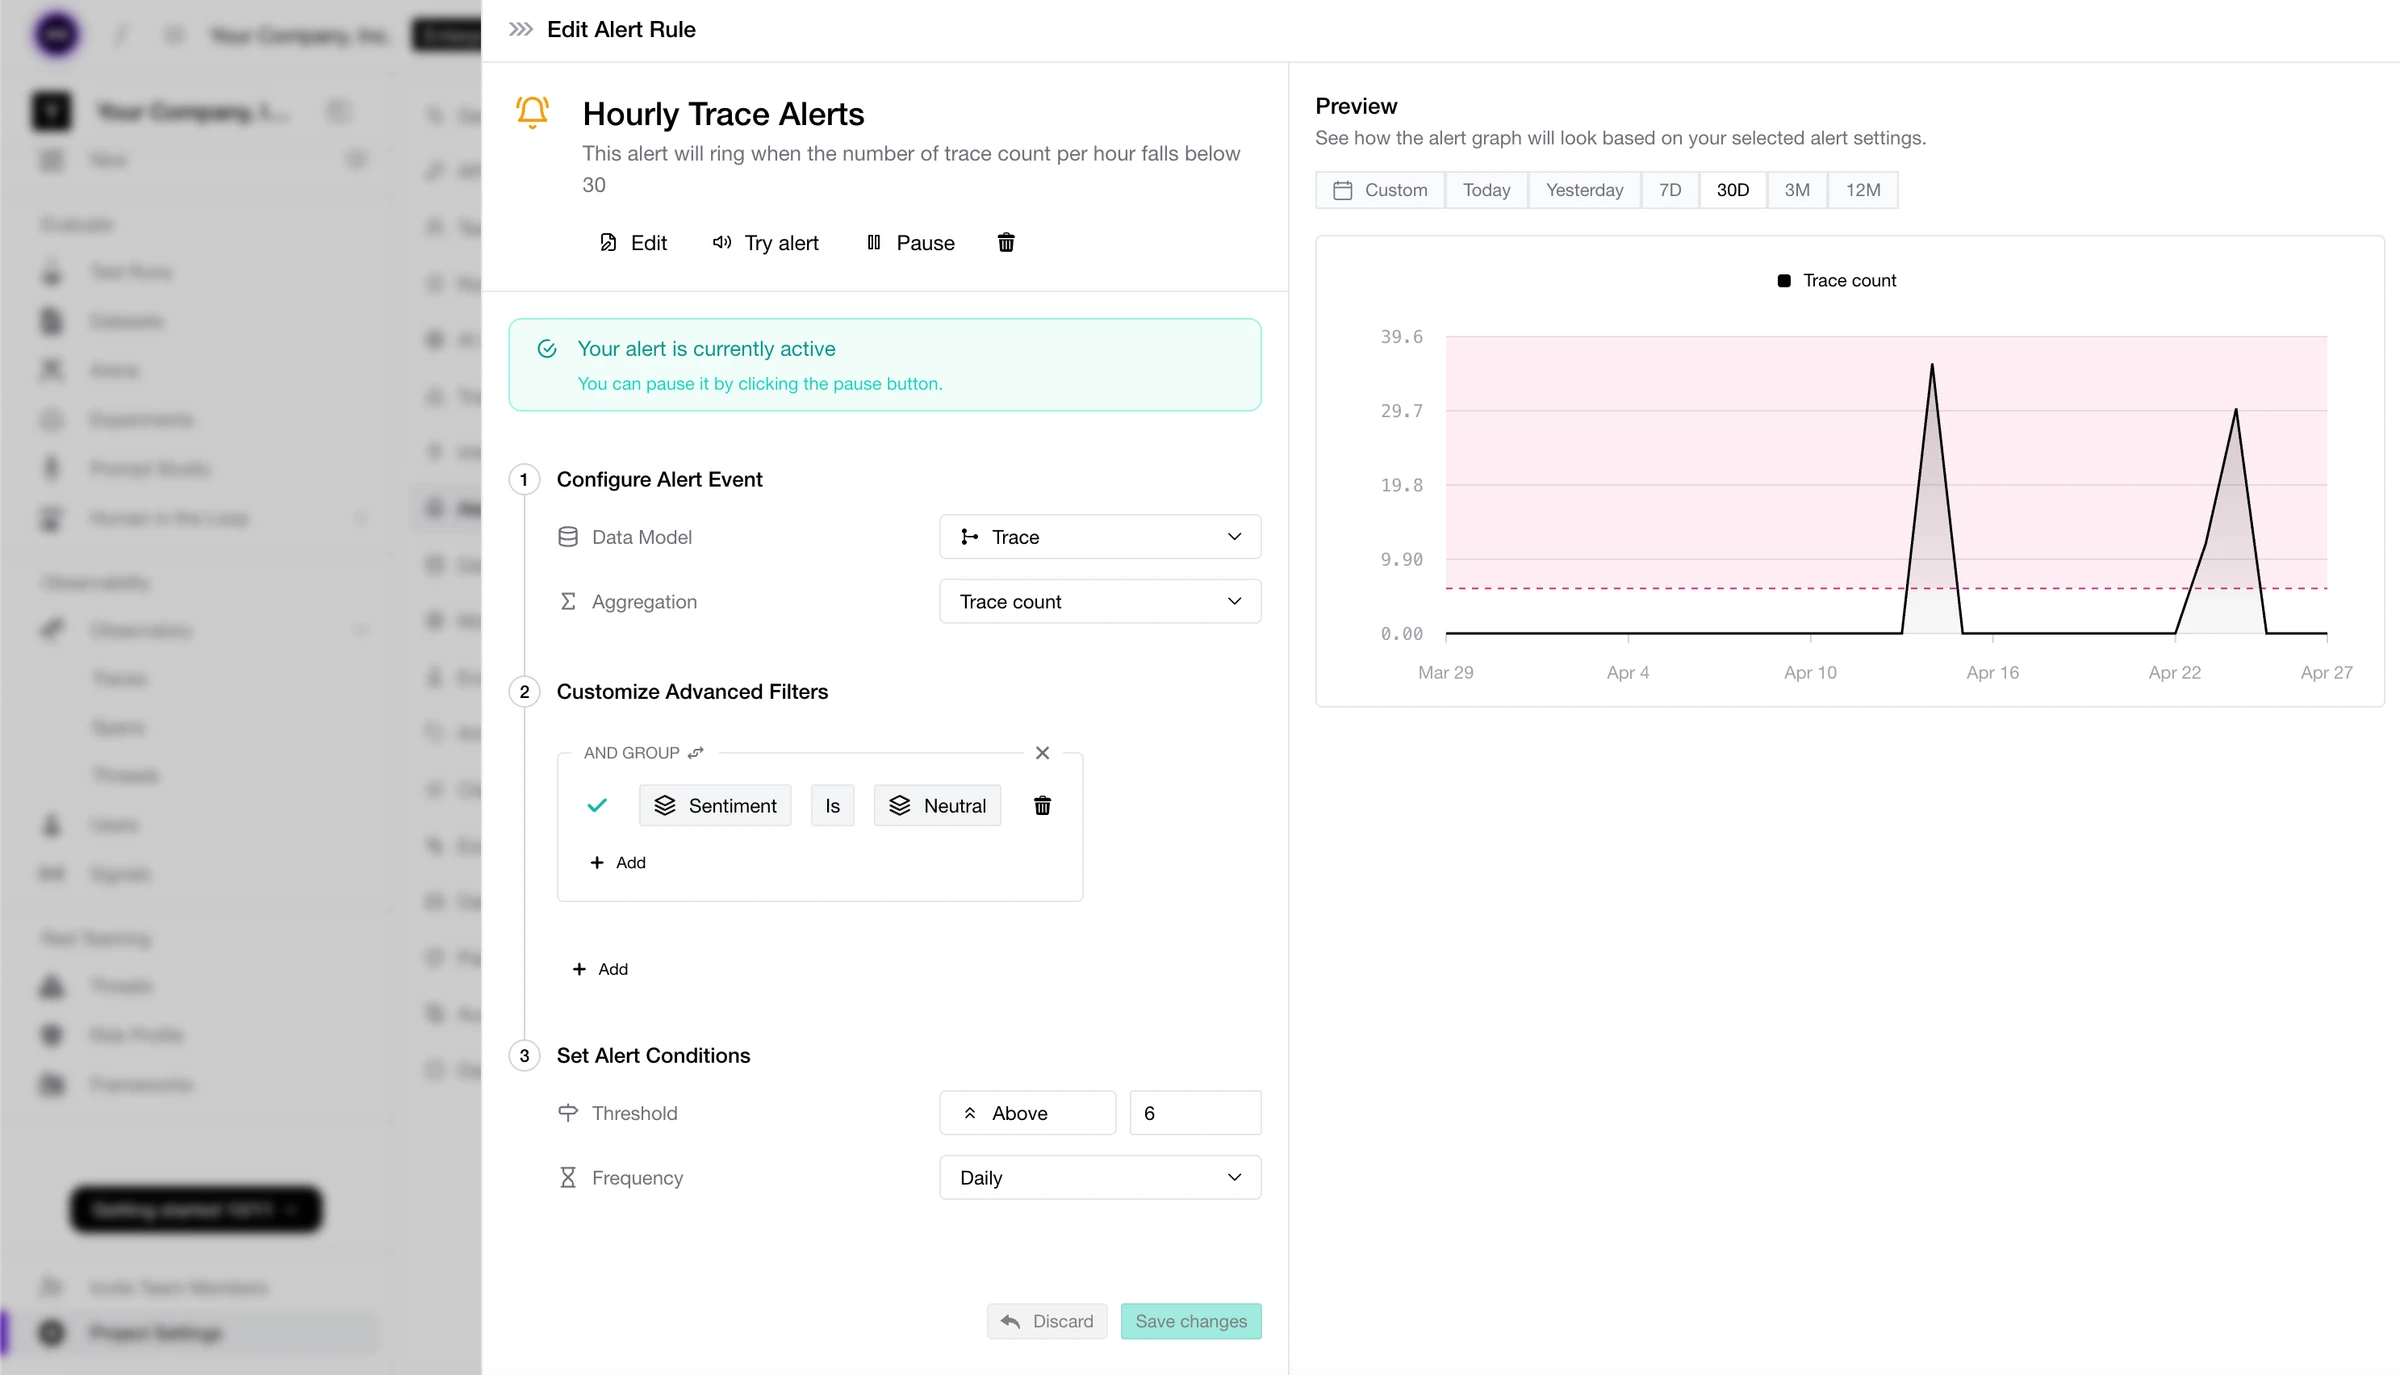
- Evals on every production trace that flag the failing ones, with alerts in Slack, PagerDuty, or Teams when quality degrades.
For platform teams
One standard. Enforced across every team.
Define the datasets, metrics and thresholds a release has to pass, and AI governance enforces them as release gates for every team. Self-host on your own infrastructure or run on our cloud. Multi-tenant by default — give every product team their own workspace with shared compliance and governance standards. Built for the AI platform team that's responsible for quality across the whole company.
- On-prem deployment in 3 days, automated updates in 30 minutes.
- SSO, RBAC, granular permissions, and audit logs.
- SOC2 Type II, GDPR-compliant, custom data retention available.
- A red-teaming module in the same system, held to the same standard.
One system for AI quality across every team: evaluation, monitoring, annotation, red teaming and governance.
Still on the fence? Talk to us.
We can only show you so much on a website. Talk to someone on the Confident AI team and see if we're a good fit.
Book a Demo